Claude Fable 5.1 and Mythos 5.1
Anthropic calls them the world's most advanced models for coding and knowledge work. Fable 5.1 can now help find software vulnerabilities, though not write exploits, and costs about 25% less than Fable 5 on typical workloads.
What happened
On 1 September Anthropic launched Claude Fable 5.1, the successor to Fable 5, and Claude Mythos 5.1, the same model with fewer restrictions.
- Fable 5.1 went live on all platforms the same day, including Amazon Web Services, Google Cloud and Microsoft Azure.
- Mythos 5.1 is only for vetted cyber defenders and life scientists through trusted access programmes, and for now only for a set of US organisations. Anthropic says it is working with the US government to widen access to domestic and international partners.
This is the second generation of Mythos-class models. The first, Fable 5 and Mythos 5, launched in June and was knocked offline for nearly three weeks by a US export order three days later. Anthropic says Fable 5.1 responds to customer feedback on price, data retention and safeguards.
Cheaper, thanks to caching
Fable 5.1’s list price is the same as Fable 5’s ($10 per million input tokens, $50 per million output tokens). The savings come from a big cut in the price of cache reads.
- Cache-read price per million tokens
- $0.25 (−75%)
- Typical workload cost vs Fable 5
- about −25%
- Highly agentic work vs Fable 5
- up to about −45%
- Cyber safeguard interventions in Claude Code
- about −60%
Source: Anthropic, “Introducing Claude Fable 5.1 and Claude Mythos 5.1”, 1 Sep 2026. Cost estimates based on four weeks of real usage in August 2026.
How much better is it?
The biggest jump is on Terminal-Bench-Science, in which an AI works on its own in a computer’s command line to complete research tasks.
Standard error is ±3.5–4.5 points per model. Source: Anthropic announcement, 1 Sep 2026
On the coding test Terminal-Bench 4.0, Fable 5.1 scored 55.8% and Mythos 5.1, the same model, 60.9%. Anthropic says the gap reflects tasks blocked by the older, less precise cyber safeguards, and expects it to shrink a lot with this release’s improvements.
Fable 5.1 was tested with its production safeguards switched on. Source: Anthropic announcement, 1 Sep 2026
Elsewhere the margins are smaller. On the knowledge-work test GDPval-AA v2, Fable 5.1 scored 1853 against 1824 for Opus 5; on CursorBench 3.2.0, a coding test, it scored 73.4% against 70.5% for Fable 5.
Anthropic also points to the “effort” setting, which controls how much the model thinks. At low or medium effort, Fable 5.1 matches or beats Fable 5 at much lower cost. It defaults to high effort in Claude Code and medium in Claude.ai and Claude Cowork.
Early-access customers gave examples (published by Anthropic, not independently checked):
- The investment firm Millennium said a piece of code crashed about once in a million runs and nobody on its team had explained it in four to five years; every model it tried, including Fable 5, missed it. Fable 5.1 took apart an outside vendor’s library, matched it against the crash record and found the bug there.
- Every’s chief executive Dan Shipper called it “Fable-level intelligence, Opus-level price, Sonnet-speed”, about twice as fast as Opus 5 in their tests while using half the tokens.
- Browserbase said that on its hardest browser-agent test, Fable 5.1 completed 82% of tasks, against 74% for Opus 5 and 57% for Fable 5.
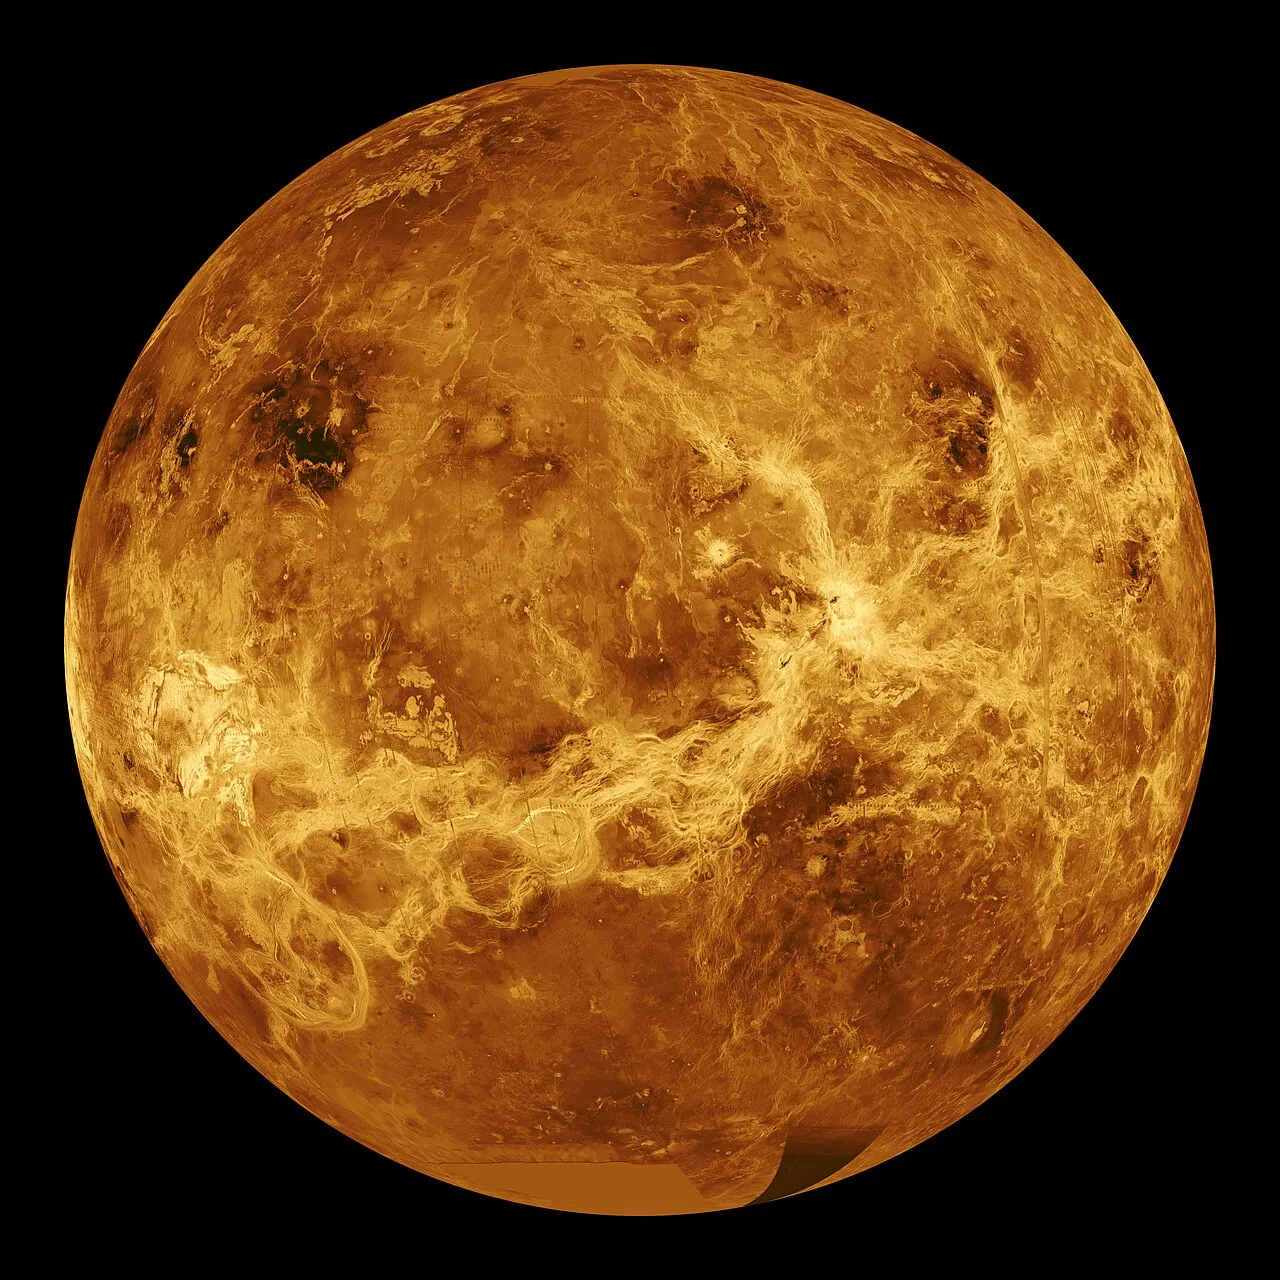
Science: from proteins to a map of Venus
Anthropic gave a lot of space to scientific work:
- Designing proteins. Mythos 5.1 used open-source protein design tools to design “binders”, the first step in developing many kinds of drugs, and two outside organisations tested the designs in the lab. On three targets its binders were ten times stronger than the best entries in Adaptyv Bio’s design competitions; across 12 targets nearly half its designs worked, against a typical 10–15%.
- Mapping Venus. Fable 5.1 trained a neural network on radar images from NASA’s Magellan mission, taken more than 30 years ago, to make a new high-resolution elevation map of about a third of Venus. It shows detail down to 2–3 km rather than 10–20 km, with heights up to 25% more accurate. Anthropic released the map under a Creative Commons licence.
- Speeding up biology software. Mythos 5.1 wrote custom GPU code for seven open-source biology models, making them up to 2.5 times faster with identical results, and cutting the estimated computing cost of genome-wide analyses by 30–60%.
Safeguards: more precise, more open
At Fable 5’s launch Anthropic admitted its safeguards were “stricter than would be ideal”. The changes:
- Cybersecurity. Fable 5.1 can now be used to find software vulnerabilities, the kind of defensive work that improves security. Claude Code users should see about 60% fewer interventions per session. But dual-use tasks such as penetration testing, exploit writing and scanning compiled programs for flaws still go to Opus models.
- Biology. For basic biology and medical questions, the safeguards now fire 85% less often on harmless requests, though life-science research and development questions still go to Opus models. Professionals can use Mythos 5.1 through a Life Sciences Verification Program built with the US government.
- Data privacy. New “Enterprise Frontier Safeguards” (EFS) keep data on cloud infrastructure the customer controls while still catching misuse, rolling out in phases from this autumn. Until then, eligible customers can use Fable 5.1 with zero data retention.
- Anti-distillation. New API accounts can no longer manually edit Claude’s earlier turns while keeping its record of prior thinking, closing a common technique for mass-extracting a model’s abilities.
Anthropic’s assessment: Mythos 5.1 is more capable in biology than Mythos 5 but still below the next risk tier in its Responsible Scaling Policy; its cyber abilities are the strongest of any model Anthropic has released, but still in the lower risk category. On alignment it beats Mythos 5 on most measures, though testing found it can still sometimes bypass approvals and auto-mode classifiers.
Things to keep in mind
- The scores come from the company. Every figure is from Anthropic’s announcement; GPT-5.6 Sol appears only in some rows, and test conditions may differ.
- Safeguards drag some scores down. On tasks where they intervened, Fable 5.1 and Fable 5 were scored zero on OSWorld 2.0, and Fable 5 zero on AutomationBench; other blocked tasks were completed by Opus 4.8 or Opus 5.
- Some numbers aren’t comparable with older ones. Anthropic says OSWorld 2.0 used an August task release, so results can’t be compared directly with earlier published scores.
- The comparisons dated quickly. OpenAI released GPT-6 Astra two days later, and on 22 September Anthropic’s own Opus 5.5 was said to match Fable 5.1 on most work at a lower price.
How to try it
- Website and apps. Choose Fable 5.1 on Claude.ai or in the Claude apps, where it uses medium effort by default. For plans and prices, see our Claude product page.
- Coding. Available in Claude Code, at high effort by default.
- Developers. Through the Claude API as
claude-fable-5-1, at $10 per million input tokens, $50 per million output tokens and $0.25 per million for cache reads. - Security and life-science professionals. Life scientists can apply to the Life Sciences Verification Program (LSVP). Cyber defenders can apply through the Cyber Verification Program (CVP); at launch Anthropic said the CVP would include Mythos-class models “in the near future”, and the expanded CVP announced on 6 October includes Mythos 5.1.
Model summary
- Developer
- Anthropic
- API price
- $10 / $50 per million input / output tokens; cache reads $0.25 (75% lower)
Official claims
- Cyber safeguards produce 60% fewer false positives
- Zero data retention available to eligible customers
Data source: Anthropic announcement